PPIO 上线 GLM-Image 部署模板,10分钟拥有私有化模型
今天,PPIO 上线图像生成领域的重磅模型——智谱 GLM-Image。
GLM-Image 利用基于GLM-4的自回归生成器进行精准的语义规划和布局,再通过扩散解码器完成高保真成像,从而具备了卓越的长文本理解力。
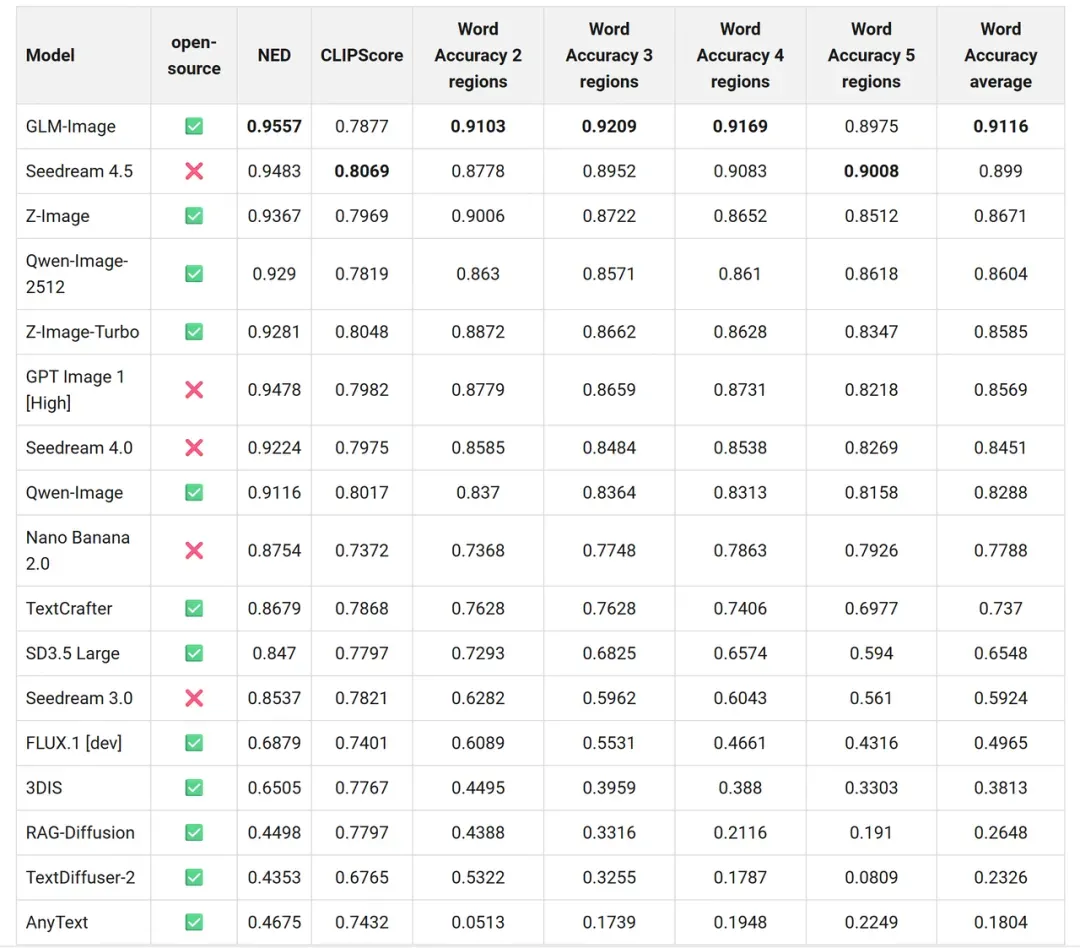
其核心突破在于SOTA级的文字渲染能力,在 CVTG-2K 基准中准确率超91%,彻底解决了AI生成海报文字乱码的行业痛点。结合GRPO美学强化学习策略,GLM-Image 在处理复杂空间关系、知识密集型绘图及图文排版任务上,展现出了远超传统纯扩散模型的表现力,是目前开源界“懂逻辑、会写字”的新一代视觉创作工具。
现在,你可以通过 PPIO 算力市场的 GLM-Image 模板,将模型一键部署在 GPU 云服务器上,简单几步就能拥有私有化的 GLM-Image 模型。
在线体验链接:
https://ppio.com/gpu-instance/console/explore?selectTemplate=select
# 01 GPU 实例+模板,一键部署 GLM-Image
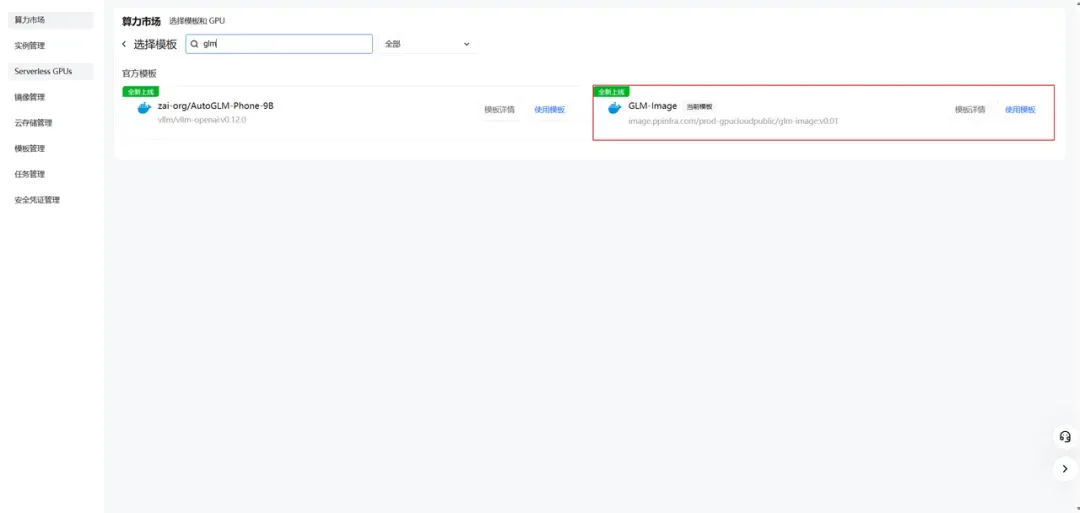
step 1:
子模版市场选择对应模板,并使用此模板。
step 2:
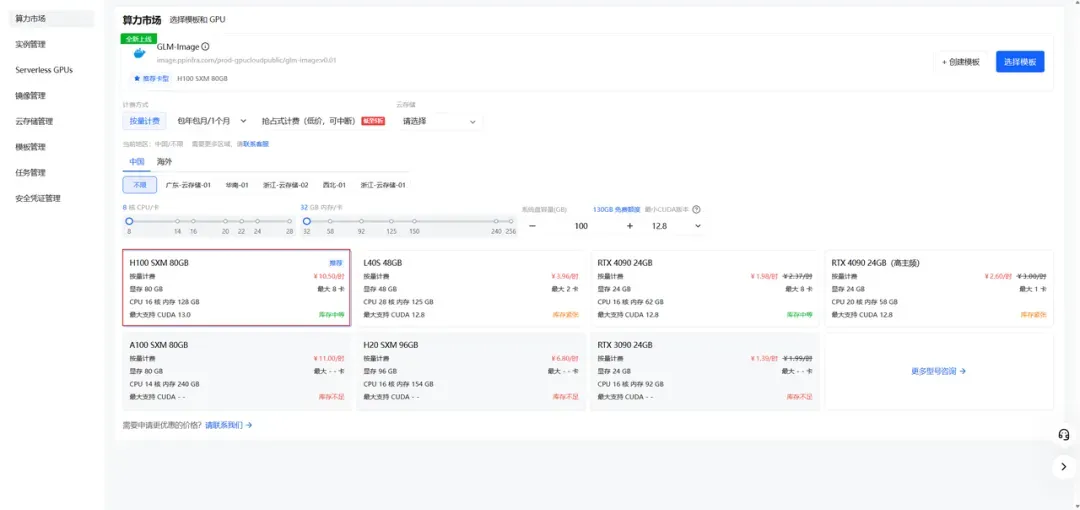
按照所需配置点击部署。
·step 3:
检查磁盘大小等信息,确认无误后点击下一步。
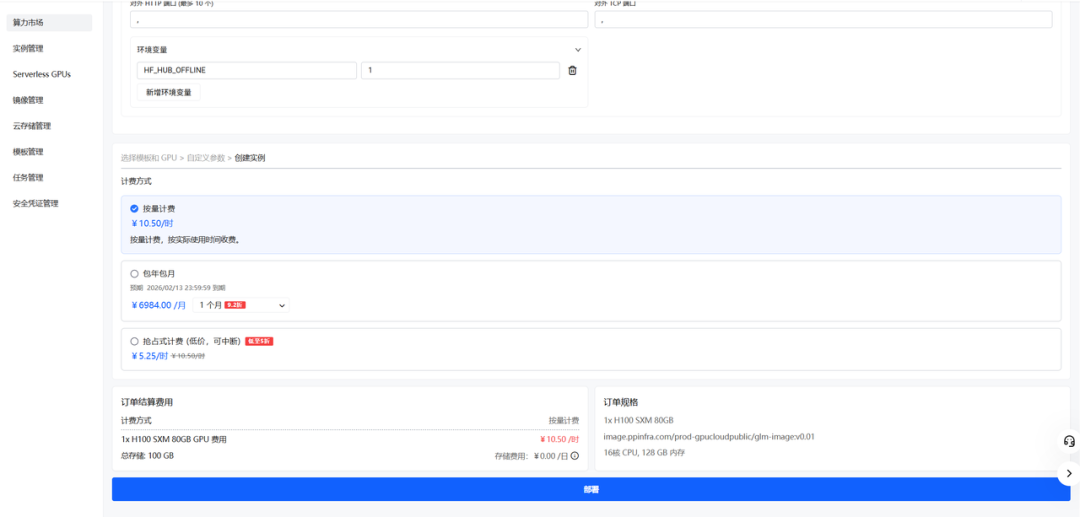
step 4
稍等一会,实例创建需要一些时间。
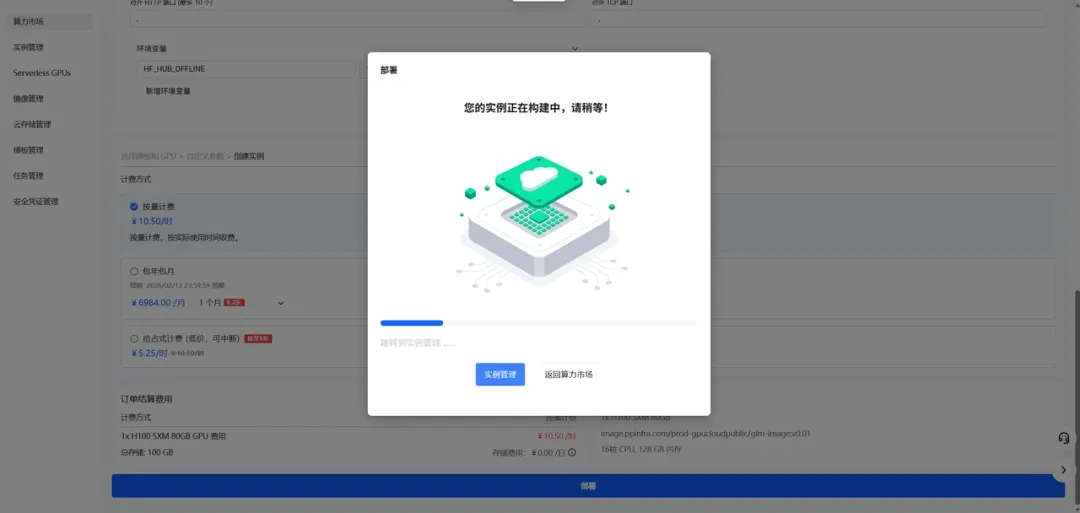
step 5:
在实例管理里可以查看到所创建的实例。
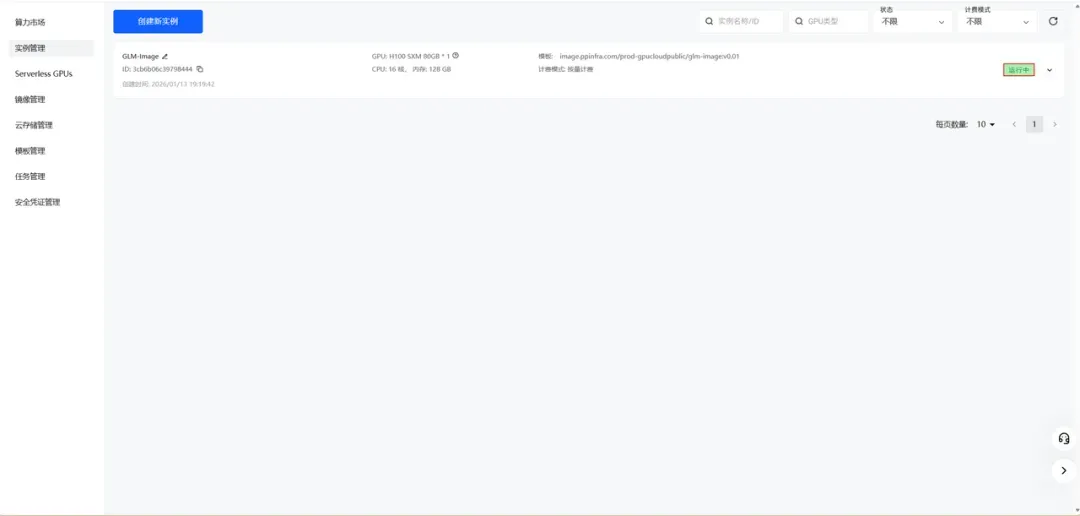
step 6:
查看实例日志,确保服务正常启动。
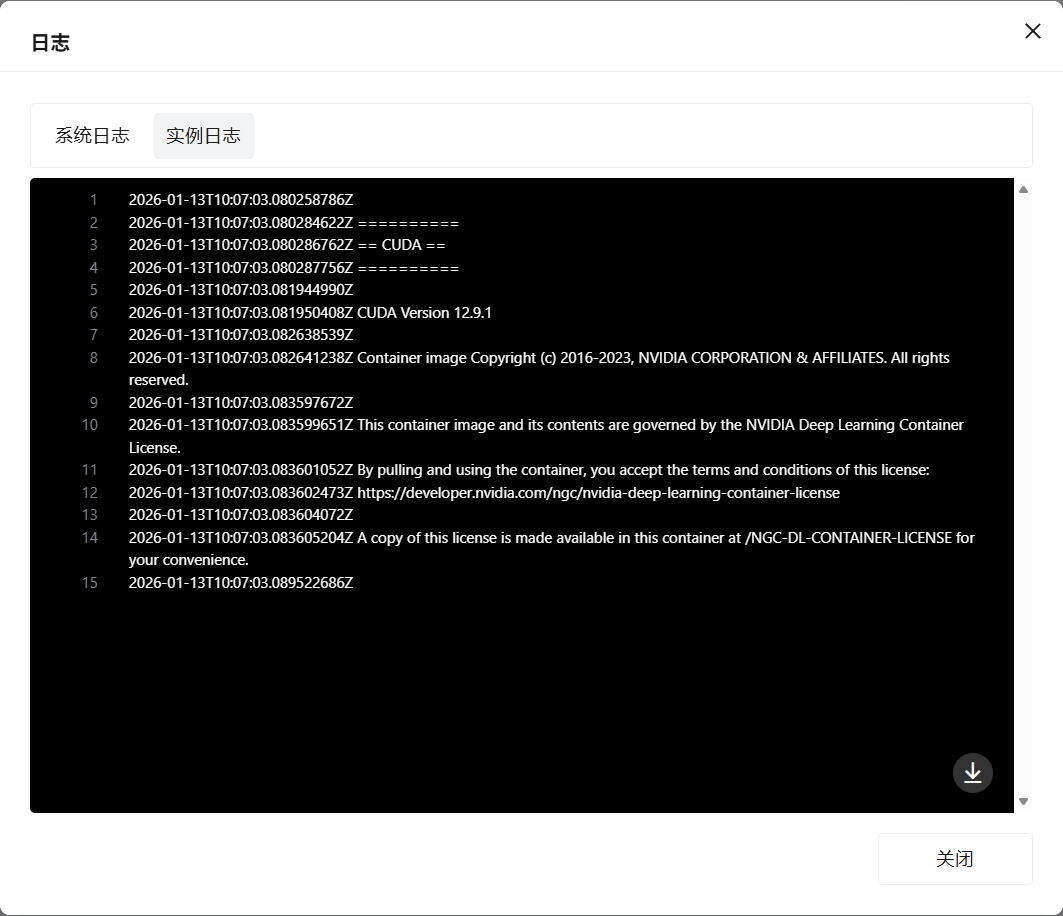
# 02 如何使用 示例 text2image.py
from diffusers.pipelines.glm_image import GlmImagePipeline

pipe = GlmImagePipeline.from_pretrained("zai-org/GLM-Image", torch_dtype=torch.bfloat16, device_map="cuda")
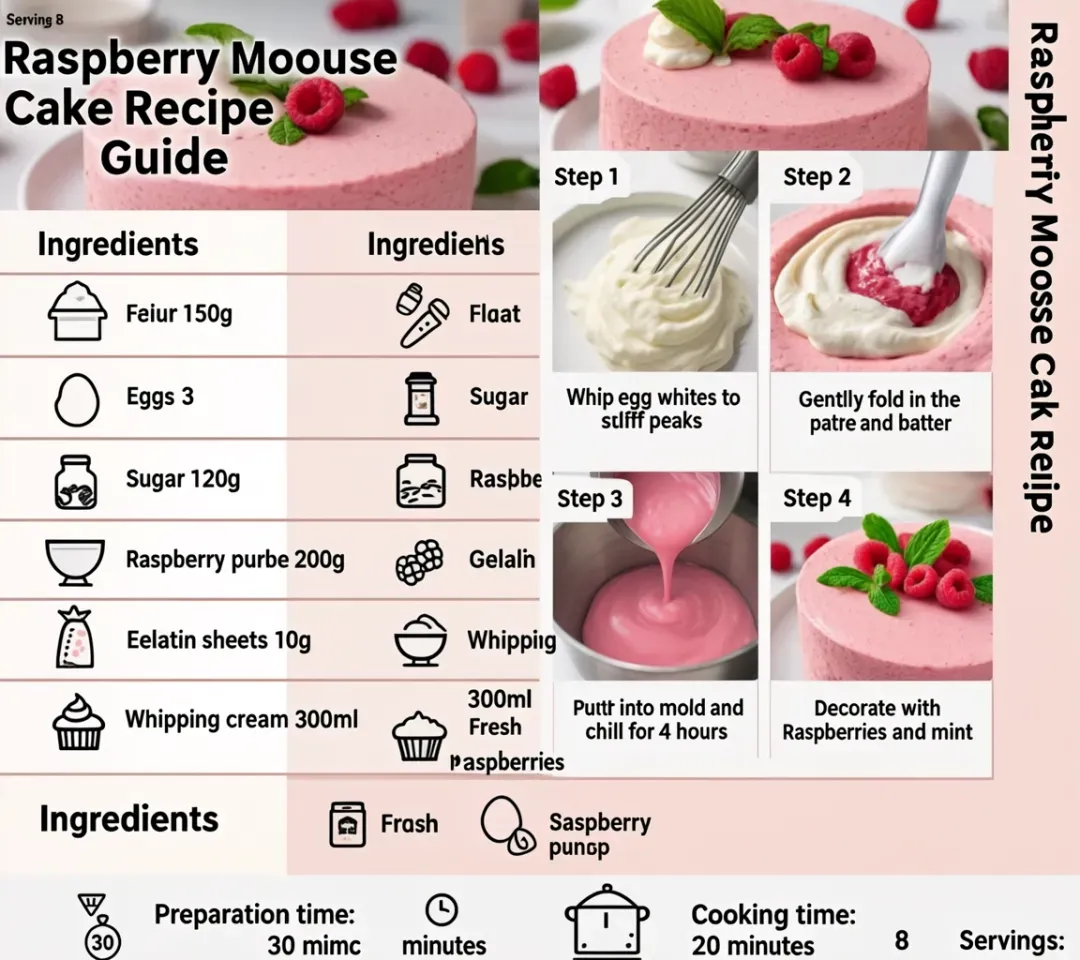
prompt = "A beautifully designed modern food magazine style dessert recipe illustration, themed around a raspberry mousse cake. The overall layout is clean and bright, divided into four main areas: the top left features a bold black title 'Raspberry Mousse Cake Recipe Guide', with a soft-lit close-up photo of the finished cake on the right, showcasing a light pink cake adorned with fresh raspberries and mint leaves; the bottom left contains an ingredient list section, titled 'Ingredients' in a simple font, listing 'Flour 150g', 'Eggs 3', 'Sugar 120g', 'Raspberry puree 200g', 'Gelatin sheets 10g', 'Whipping cream 300ml', and 'Fresh raspberries', each accompanied by minimalist line icons (like a flour bag, eggs, sugar jar, etc.); the bottom right displays four equally sized step boxes, each containing high-definition macro photos and corresponding instructions, arranged from top to bottom as follows: Step 1 shows a whisk whipping white foam (with the instruction 'Whip egg whites to stiff peaks'), Step 2 shows a red-and-white mixture being folded with a spatula (with the instruction 'Gently fold in the puree and batter'), Step 3 shows pink liquid being poured into a round mold (with the instruction 'Pour into mold and chill for 4 hours'), Step 4 shows the finished cake decorated with raspberries and mint leaves (with the instruction 'Decorate with raspberries and mint'); a light brown information bar runs along the bottom edge, with icons on the left representing 'Preparation time: 30 minutes', 'Cooking time: 20 minutes', and 'Servings: 8'. The overall color scheme is dominated by creamy white and light pink, with a subtle paper texture in the background, featuring compact and orderly text and image layout with clear information hierarchy."
image = pipe(
    prompt=prompt,
    height=32 * 32,
    width=36 * 32,
    num_inference_steps=30,
    guidance_scale=1.5,
    generator=torch.Generator(device="cuda").manual_seed(42),
).images[0]
image.save("output_t2i.png")
你可以通过修改 text2image.py 中的 prompt 来运行或者直接使用现有的案例运行。
python3 text2image.py
Couldn't connect to the Hub: Cannot reach https://huggingface.co/api/models/zai-org/GLM-Image: offline mode is enabled. To disable it, please unset the `HF_HUB_OFFLINE` environment variable..
Will try to load from local cache.
Loading checkpoint shards: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 3/3 [00:02<00:00,  1.47it/s]
Loading weights: 100%|█████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 111/111 [00:00<00:00, 1391.52it/s, Materializing param=shared.weight]
Loading pipeline components...:  71%|██████████████████████████████████████████████████████████████████████████████████████████████████████▏                                        | 5/7 [00:02<00:00,  2.91it/s]Using a slow image processor as `use_fast` is unset and a slow processor was saved with this model. `use_fast=True` will be the default behavior in v4.52, even if the model was saved with a slow processor. This will result in minor differences in outputs. You'll still be able to use a slow processor with`use_fast=False`.
Loading weights: 100%|██████████████████████████████████████████████████████████████████████████████████████████| 1011/1011 [00:02<00:00, 359.59it/s, Materializing param=model.vqmodel.quantize.embedding.weight]
Loading pipeline components...: 100%|███████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 7/7 [00:07<00:00,  1.02s/it]
100%|█████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 30/30 [00:11<00:00,  2.69it/s]
output_t2i.png
示例 image2image.py
import torch
from diffusers.pipelines.glm_image import GlmImagePipeline
from PIL import Image
pipe = GlmImagePipeline.from_pretrained("zai-org/GLM-Image", torch_dtype=torch.bfloat16, device_map="cuda")
image_path = "cond.jpg"
prompt = "Replace the background of the snow forest with an underground station featuring an automatic escalator."
image = Image.open(image_path).convert("RGB")
image = pipe(
    prompt=prompt,
    image=[image],  # can input multiple images for multi-image-to-image generation such as [image, image1]
    height=33 * 32,
    width=32 * 32,
    num_inference_steps=30,
    guidance_scale=1.5,
    generator=torch.Generator(device="cuda").manual_seed(42),                                                           ).images[0]
image.save("output_i2i.png")
python3 image2image.py
你可以通过修改 image2image.py 中的 prompt 和 image 来运行 或者直接使用现有的案例运行
python3 image2image.py
Couldn't connect to the Hub: Cannot reach https://huggingface.co/api/models/zai-org/GLM-Image: offline mode is enabled. To disable it, please unset the `HF_HUB_OFFLINE` environment variable..
Will try to load from local cache.
Loading pipeline components...:   0%|                                                                                                                                                       | 0/7 [00:00<?, ?it/s]Using a slow image processor as `use_fast` is unset and a slow processor was saved with this model. `use_fast=True` will be the default behavior in v4.52, even if the model was saved with a slow processor. This will result in minor differences in outputs. You'll still be able to use a slow processor with`use_fast=False`.
Loading weights: 100%|██████████████████████████████████████████████████████████████████████████████████████████| 1011/1011 [00:02<00:00, 360.88it/s, Materializing param=model.vqmodel.quantize.embedding.weight]
Loading checkpoint shards: 100%|████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 3/3 [00:02<00:00,  1.46it/s]
Loading weights: 100%|█████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 111/111 [00:00<00:00, 1426.62it/s, Materializing param=shared.weight]
Loading pipeline components...: 100%|███████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████████| 7/7 [00:07<00:00,  1.03s/it]
100%|███████████████████████████████████████████████████████████████████████████████████| 30/30 [00:10<00:00,  2.97it/s]
# 03 结语
PPIO 的算力市场模板致力于帮助企业及个人开发者降低大模型私有化部署的门槛,无需繁琐的环境配置,即可实现高效、安全的模型落地。
目前,PPIO算力市场已上线几十个私有化部署模板,除了 GLM-Image,你也可以将 AutoGLM-Phone-9B、Nemotron Speech ASR、PaddleOCR-VL 等模型快速进行私有化部署。